Tag: large language models - Page 2
Curriculum Learning in NLP: How Ordering Data Makes Large Language Models Smarter
Curriculum learning in NLP improves large language models by training them on data ordered from simple to complex, cutting costs, speeding up training, and boosting accuracy on hard tasks. Learn how it works and where it shines.
Read More
Model Parallelism and Pipeline Parallelism in Large Generative AI Training
Model and pipeline parallelism enable training of massive generative AI models by splitting them across multiple GPUs. Learn how these techniques overcome GPU memory limits and power models like GPT-3 and Claude 2.
Read More
Governance Policies for LLM Use: Data, Safety, and Compliance in 2025
In 2025, U.S. governance policies for LLMs demand strict controls on data, safety, and compliance. Federal rules push innovation, but states like California enforce stricter safeguards. Know your obligations before you deploy.
Read More
Multi-Head Attention in Large Language Models: How Parallel Perspectives Power Modern AI
Multi-head attention lets large language models understand language from multiple angles at once, enabling breakthroughs in context, grammar, and meaning. Learn how it works, why it dominates AI, and what's next.
Read More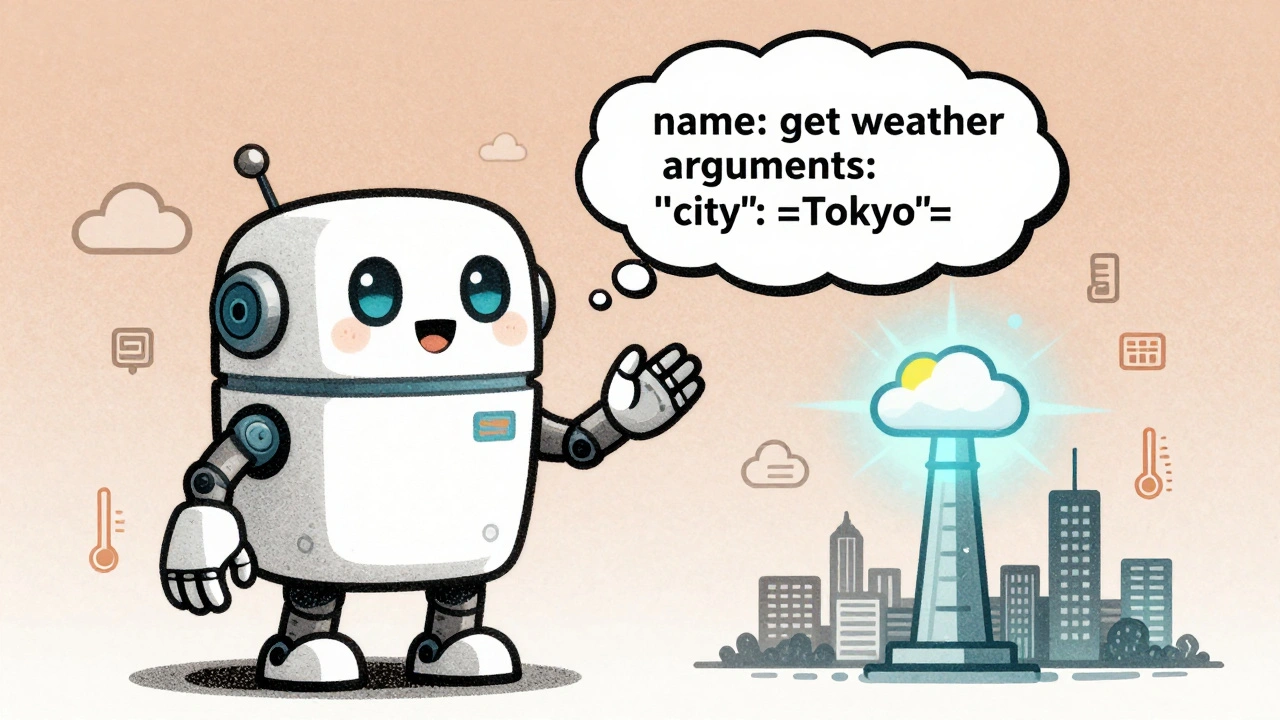
Tool Use with Large Language Models: Function Calling and External APIs Explained
Function calling lets large language models interact with real tools and APIs to access live data, reducing hallucinations and improving accuracy. Learn how it works, how major models compare, and how to build it safely.
Read More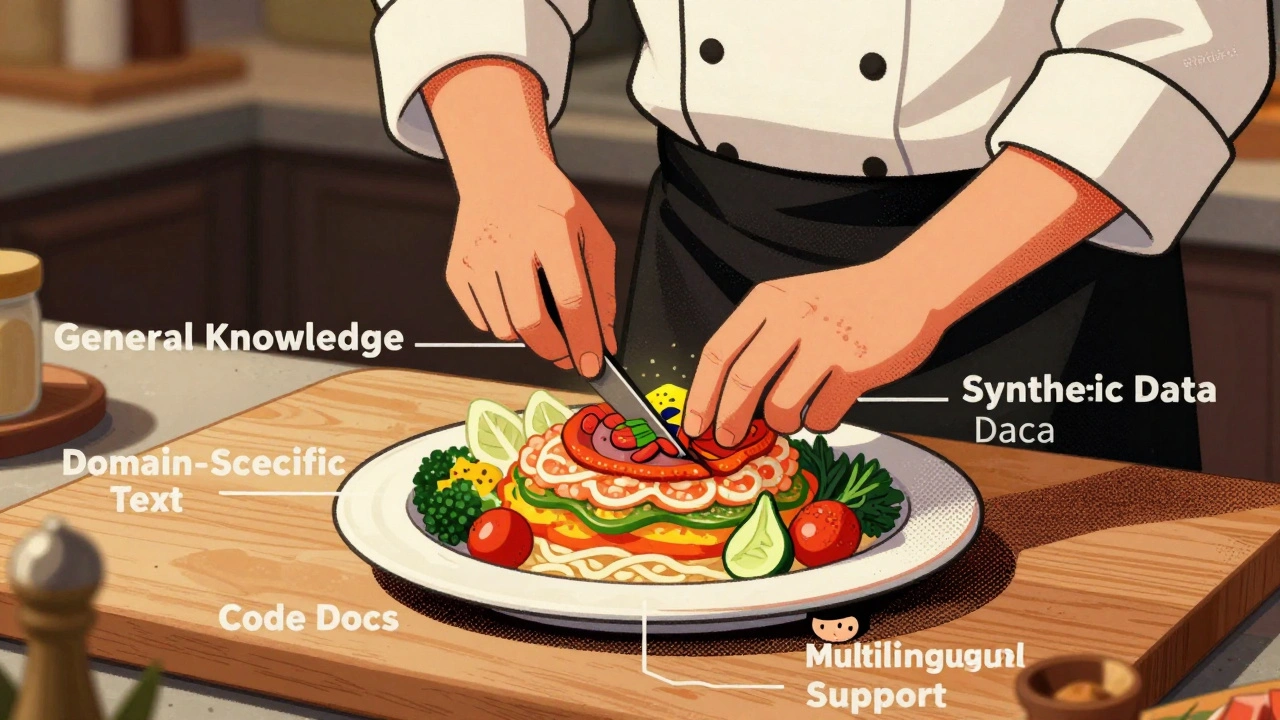
How to Build a Domain-Aware LLM: The Right Pretraining Corpus Composition
Learn how to build domain-aware LLMs by strategically composing pretraining corpora with the right mix of data types, ratios, and preprocessing techniques to boost accuracy while reducing costs.
Read More
Distributed Training at Scale: How Thousands of GPUs Power Large Language Models
Distributed training at scale lets companies train massive LLMs using thousands of GPUs. Learn how hybrid parallelism, hardware limits, and communication overhead shape real-world AI training today.
Read More