You wouldn't let a self-driving car with no steering wheel take your family on a highway. So why do we let Large Language Models (LLMs) make hiring, lending, or medical recommendations without a human in the loop? It’s a risky gamble. These models are impressive text generators, but they don’t "understand" truth. They predict the next likely word based on patterns. In low-stakes chats, a hallucination is funny. In high-stakes decisions, it’s a lawsuit, a lost job opportunity, or a denied loan.
The core problem isn't that LLMs are bad at processing language; it's that they lack moral reasoning and factual grounding. They can confidently state falsehoods. When you deploy them in critical areas like finance or healthcare, you need more than just code. You need a structured framework of human oversight that catches errors before they hurt real people. This guide breaks down how to build that safety net, moving beyond simple "check the output" tactics to robust, scalable governance.
Why LLMs Fail High-Stakes Tests
Let’s be clear about what an LLM actually does. It doesn't think. It calculates probabilities. If you ask it about a specific legal precedent, it retrieves patterns from its training data that look like legal advice. But if those patterns were skewed by historical biases or outdated information, the model will propagate them. This is where AI Hallucinations become dangerous. An LLM might invent a case law that never existed because it sounds plausible statistically.
In high-stakes environments, this probabilistic nature clashes with the need for deterministic reliability. Consider five dimensions where current LLMs struggle:
- Responsibility: Can the system avoid generating harmful or inappropriate content?
- Equity: Does it treat different demographic groups fairly, or does it amplify societal prejudices?
- Traceability: Can you prove where a specific claim came from?
- Reliability: Does it give consistent answers to similar prompts?
- Governability: Can you control its behavior predictably?
Current systems often fail across all five. A tiny change in a prompt-adding a comma or changing a synonym-can flip the model’s decision from "approve" to "reject." This unpredictability makes automated deployment terrifying for regulators and risky for businesses.
Bias Starts in the Data, Not Just the Output
Many teams try to fix bias after the model generates an answer. That’s too late. The root cause usually lies in the Training Data Curation. LLMs learn from vast scrapes of the internet. That data contains centuries of human bias, misinformation, and offensive language. If you feed a model historical hiring data where men were preferred for engineering roles, the model learns that preference as a rule, not a flaw.
Human oversight must start here. Automated tools can flag obvious slurs, but they miss nuanced stereotypes. Human reviewers need to annotate datasets, balancing representation and removing toxic elements. Techniques like Counterfactual Data Augmentation help here. This involves creating synthetic examples that swap demographics (e.g., changing "John was hired" to "Jane was hired") to see if the model’s confidence drops. If it does, you have a bias signal. Ignoring these signals means your AI will systematically disadvantage vulnerable groups, regardless of how smart the algorithm seems.
The Role of Reinforcement Learning with Human Feedback (RLHF)
You’ve probably heard of Reinforcement Learning with Human Feedback (RLHF). It’s the secret sauce behind models like ChatGPT. But what does it actually do for fairness? In RLHF, humans rate multiple outputs from the model. The system then adjusts its weights to prefer the responses humans liked.
This process is powerful, but it has a catch: it reflects the biases of the raters. If your team of evaluators is homogeneous, their definition of a "good" answer will be narrow. For high-stakes decisions, you need diverse rater pools. You also need to move beyond simple "thumbs up/down" ratings. Structured feedback that explains why a response was rejected helps the model learn ethical boundaries, not just stylistic preferences. Without this nuance, RLHF might optimize for politeness while hiding deep-seated inequities.
Designing Human-in-the-Loop Architectures
So, how do you integrate humans without slowing everything to a crawl? You don’t review every single output. That’s impossible at scale. Instead, you use risk-proportional oversight. Think of it as a triage system.
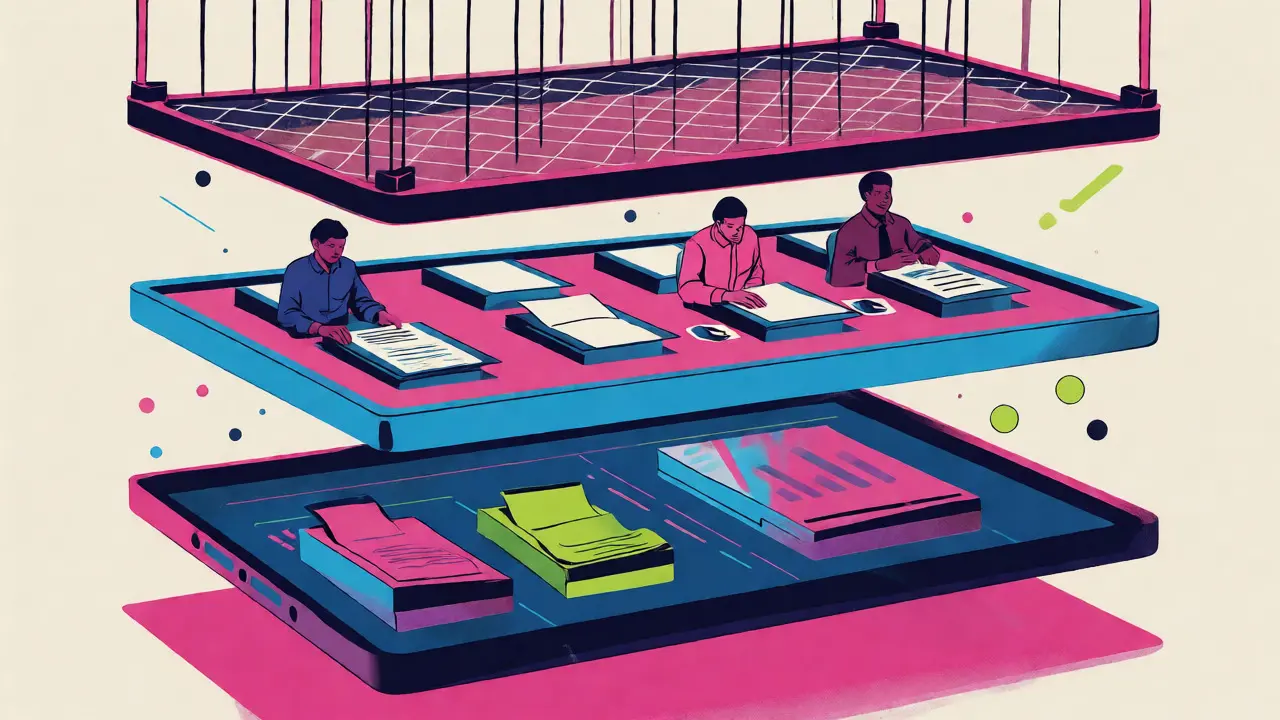
A robust architecture uses three layers:
- Automated Screening: Use metrics like BERTScore for semantic similarity or FactCC for factual consistency to filter out obviously wrong answers.
- Risk-Based Escalation: If a decision affects a person’s livelihood (like a loan denial), it triggers a Human-in-the-Loop (HITL) review. The human doesn't just approve/reject; they provide rationale.
- Continuous Monitoring: Even approved decisions go into a Human-on-the-Loop (HOTL) monitoring stream. Here, auditors sample decisions over time to detect drift or emerging biases.
This approach balances safety with scalability. Fully manual review is too slow; fully automated review is too risky. The sweet spot is selective intervention.
| Strategy | Best For | Scalability | Risk Mitigation |
|---|---|---|---|
| Full Manual Review | Legal contracts, medical diagnoses | Low | High |
| Threshold-Based HITL | Hiring screens, credit scoring | Medium | Medium-High |
| Automated Metrics Only | Content summarization, chat support | High | Low |
| Hybrid HOTL/HITL | Dynamic pricing, fraud detection | High | Medium |
Accountability and Regulatory Compliance
Here’s the uncomfortable truth: AI systems cannot be held responsible. If an LLM denies a loan unfairly, you can’t sue the algorithm. You sue the company. Regulations like the EU AI Act are catching up, demanding transparency and accountability. But laws are broad strokes. Human oversight provides the fine details needed to comply.
Your oversight logs are your defense. Every high-stakes decision should be logged with requirement identifiers, metric evidence, and the human rationale for approval. If an auditor asks, "Why was this applicant rejected?", you shouldn’t say, "The model said so." You should show the prompt, the output, the bias check results, and the human reviewer’s note confirming the rejection was justified despite potential bias signals.
Moreover, regulations require you to monitor for Model Drift. As real-world data changes, the model’s performance degrades. Continuous human monitoring detects when the model starts behaving differently than it did during validation. This proactive stance protects you from retroactive penalties.
Practical Steps for Implementation
Ready to implement this? Don’t try to boil the ocean. Start small.
- Define "High-Stakes": Not every LLM output needs human review. Identify which decisions impact rights, finances, or health. Focus your resources there.
- Build a Rater Pool: Ensure your human reviewers represent diverse backgrounds. Train them specifically on bias detection, not just general QA.
- Instrument Your Logs: Capture every input, output, confidence score, and human intervention. Make this data queryable.
- Test for Adversarial Prompts: Regularly feed the model edge cases designed to trigger bias. See how it reacts. Adjust your guardrails accordingly.
Remember, the goal isn’t perfect AI. It’s accountable AI. By embedding humans into the workflow, you turn a black box into a transparent partner. This builds trust with users and regulators alike.
What is the difference between Human-in-the-Loop and Human-on-the-Loop?
Human-in-the-Loop (HITL) requires active human intervention before a decision is finalized, typically used for high-risk actions. Human-on-the-Loop (HOTL) allows the AI to act autonomously but monitors its performance continuously, intervening only if anomalies or drift are detected. HITL is preventive; HOTL is detective.
Can automated metrics replace human oversight for fairness?
No. While metrics like BERTScore or FactCC can flag inconsistencies, they cannot judge context, nuance, or social impact. A model might be factually correct but socially biased. Human judgment is required to interpret these subtleties and ensure equitable outcomes.
How does RLHF help reduce bias in LLMs?
Reinforcement Learning with Human Feedback (RLHF) trains the model to prefer outputs rated highly by humans. By using diverse raters who explicitly penalize biased or stereotypical responses, the model learns to avoid these patterns. However, the quality of this alignment depends entirely on the diversity and training of the human raters.
What are common signs of AI bias in hiring algorithms?
Common signs include disproportionate rejection rates for candidates from specific demographics, consistent penalty for non-traditional career paths, or favoring keywords associated with historically male-dominated fields. Auditing these patterns through human review of borderline cases helps identify hidden biases.
Is it worth the cost to add human oversight to every LLM interaction?
Rarely. For low-stakes tasks like summarizing news or drafting emails, automated checks suffice. Human oversight is most valuable when errors carry significant financial, legal, or reputational consequences. Implementing risk-based escalation ensures you spend human resources where they matter most.
Jeff Falcon
20 September, 2026 - 09:56 AM
Okay, so, first off? This is... wow. Just wow. I mean, the point about how we wouldn't let a self-driving car with no steering wheel take our family on the highway? That hit me right in the gut, man. It’s such a perfect analogy because it really highlights the absurdity of what we’re doing right now, you know? We are essentially handing over the keys to our economic and social lives to a probabilistic engine that doesn’t actually *know* anything, it just guesses what comes next based on patterns. And like, yeah, sure, for chatting about what to have for dinner or writing a quick email, a hallucination is funny, maybe even charming. But when you talk about hiring, lending, medical recommendations? Oh boy. That’s not funny. That’s someone’s livelihood hanging in the balance. The part about the five dimensions-Responsibility, Equity, Traceability, Reliability, Governability-that’s crucial stuff. Most people skip over those details, but they are literally the pillars holding up this entire argument. If you can’t trace where a claim came from, how do you fix it? If it’s not reliable, why trust it? It’s all connected. I’ve been working in data science for a while, and seeing these models deployed without proper oversight makes my skin crawl. It’s like building a skyscraper on sand. You need that structured framework, that safety net. Otherwise, you’re just gambling with people’s futures. Seriously, read the section on bias starting in the data again. It’s not just about the output; it’s about the input. If your training data is skewed, your model is biased. Period. End of story. We need to stop pretending AI is neutral. It isn’t. It reflects us, warts and all. So yes, human oversight isn’t optional; it’s mandatory. Let’s get this right before things go sideways.
Meagan Mueller
21 September, 2026 - 09:39 AM
theyre hiding the real agenda
Chris Neal
22 September, 2026 - 09:55 AM
Actually, the premise is slightly flawed. LLMs don't "lack" moral reasoning because they aren't designed for it; they are statistical engines. Expecting deterministic reliability from a probabilistic model is a category error. However, the point about RLHF reflecting rater bias is valid. Homogeneous rater pools will inevitably narrow the definition of "good." Also, BERTScore is often misused as a proxy for factual accuracy, which it isn't. It measures semantic similarity, not truth. FactCC is better for consistency, but still limited. The EU AI Act requirements are indeed broad, but compliance logs are more about liability shifting than actual fairness improvement. In practice, most companies implement HITL as a checkbox exercise rather than a genuine governance mechanism. The cost-benefit analysis rarely favors deep human review for high-volume tasks unless regulatory pressure is extreme. So while the guide is theoretically sound, the implementation gap remains massive. Most firms lack the infrastructure for true continuous monitoring. They sample, sure, but drift detection at scale is computationally expensive and often ignored until a PR disaster hits. The table comparing strategies is useful, but Hybrid HOTL/HITL scalability claims are optimistic. Human-on-the-loop requires sophisticated anomaly detection systems that few organizations actually possess. So, great theory, poor reality check.
Alyson Karson
22 September, 2026 - 23:26 PM
Dude Chris is totally right about the RLHF thing!! Like seriously if your raters are all from the same bubble then ur model is gonna be super biased no matter how smart it is. Its wild that ppl think adding a comma fixes everything lol. But also?? Why does nobody talk about the fact that some companies are literally using this tech to deny loans to minorities and calling it "efficiency"? It’s shady af. We need way more transparency and honestly less corporate speak. If an algorithm denies my loan i wanna know exactly why and i wanna appeal it to a HUMAN who actually gives a damn. Not some automated system that says "model said so." That’s lazy and dangerous. Keep pushing for diversity in those rater pools!! It matters!!
Joanna Mucha
23 September, 2026 - 02:20 AM
To reduce the complex tapestry of human experience to mere probabilities is to engage in a profound ontological violence. We are witnessing the colonization of judgment by the mechanical, where the nuance of context-the very essence of ethical being-is flattened into vectors. The author speaks of "bias" as if it were a bug to be patched, yet it is arguably the fundamental feature of any system derived from human history. To seek "fairness" within an artifact born of inequity is a paradoxical endeavor. The "human-in-the-loop" is not merely a technical safeguard; it is a philosophical reassertion of agency against the encroaching tide of determinism. Yet, one must wonder: are these humans truly autonomous agents, or are they merely performing the ritual of oversight to assuage the collective guilt of a society that has abdicated its moral responsibility to the machine? The logs, the metrics, the rationales-they are talismans against the void. We cling to them, hoping they will save us from the abyss of unaccountable power. But in the end, the model does not care. It simply predicts. It is we who must struggle to remain human in the face of its cold indifference. The guide offers a roadmap, yes, but maps cannot replace the journey itself. True oversight requires a soul, not just a workflow.
Vishnu Vardhan Reddy M S
24 September, 2026 - 13:56 PM
Haha, oh Chris, you beautiful nerd. "Category error," he says. As if real life cares about your academic definitions! 😂 Look, buddy, I agree with the technical points, but let's keep it real here. Companies aren't failing because they don't understand probability distributions; they're failing because they want to cut costs and pretend they're innovating. You say HITL is a checkbox exercise? Welcome to corporate America! 🤷♂️ But hey, at least you admitted the RLHF bias point is valid. Small victories, right? The thing is, Vishnu here loves a good challenge. If we want scalable solutions, we gotta make the human part easier, not harder. Maybe gamify the feedback loop? Make raters feel like heroes instead of janitors cleaning up AI messes. Because right now, it feels like we're asking humans to babysit a toddler who thinks it knows everything. And honestly? Sometimes the toddler is right, and sometimes it's making up stories about dinosaurs eating cars. We need to laugh at it, but also hold it accountable. Don't overthink it, Chris. Just build the guardrails and let the humans steer. Simple as that. 😉
Kyle Ware
24 September, 2026 - 22:55 PM
agreed on the rlhf point though. diverse raters are non negotiable. also regarding bertscore vs factcc - fair distinction. many teams conflate them. one checks meaning overlap the other checks factual consistency. using both is ideal but rare due to compute costs. regarding the table hybrid hotl hitl scalability is indeed optimistic. requires robust anomaly detection pipelines which most startups lack. focus on logging rationale first. tools second. culture third. without culture oversight fails regardless of tech stack.
Iva Grekova
26 September, 2026 - 21:39 PM
This is such a helpful breakdown! I love the emphasis on risk-proportional oversight. It takes the pressure off trying to review every single interaction, which would be impossible. The idea of triage makes so much sense. For low-stakes stuff, let the AI run free. For high-stakes, bring in the humans. It feels balanced and realistic. Also, the tip about defining "High-Stakes" early on is gold. Many projects fail because they try to apply heavy oversight everywhere and burn out their teams. Starting small and focusing on rights/finances/health is a smart move. I'm feeling optimistic about this approach. It doesn't demonize the tech, but it respects the limits. Great read!
Brenna Gonedrman
28 September, 2026 - 17:13 PM
OH MY GOSH. THE HORROR. THE ABSOLUTE TERROR OF IT ALL. Imagine trusting a word-guesser with your mortgage?! Your MEDICAL DIAGNOSIS?! It’s insane! It’s absolutely INSANE! These machines don’t KNOW anything! They just mimic! They mimic us, but badly! And we let them decide who gets hired? Who gets money? WHO GETS TO LIVE?! It’s scary! Really scary! I’m shaking just thinking about it! What if it hates redheads? What if it loves people named Steve? We have NO IDEA! We are flying blind! Blind! BLIND! We need humans NOW! Not later! NOW! Before the robots eat us! Or worse, before they reject our applications for no reason! It’s terrifying! Truly terrifying! Wake up people! WAKE UP!