Imagine reading a sentence where the words are scrambled: "mat on sat cat The." You can probably figure out what it means, even though the grammar is broken. Now imagine trying to explain that same meaning to a computer that reads every word at the exact same time. That’s the core problem with Transformers, the architecture behind most modern Large Language Models (LLMs). Unlike humans or older AI models that read left-to-right, Transformers process all tokens in parallel. Without help, they have no idea which word came first. This is where positional information steps in.
If you’ve ever wondered how an AI knows the difference between "Dog bites man" and "Man bites dog," despite seeing both sentences simultaneously, this article breaks down the mechanics. We’ll look at why position matters, how different encoding methods work, and why the industry is currently shifting away from simple absolute positions toward more complex, relative solutions like Rotary Position Embedding (RoPE).
The Parallel Processing Paradox
To understand why positional encoding is necessary, you have to look at how Recurrent Neural Networks (RNNs) worked versus how Transformers work today. RNNs were sequential. They processed one word, updated their memory, then moved to the next. The position was inherent in the timing of the processing. If a word arrived third, the model knew it was third because two updates had already happened.
Transformers, introduced in the seminal 2017 paper "Attention is All You Need," ditched this sequence for speed. By using self-attention mechanisms, they could look at every word in a sentence at once. This allowed for massive parallelization on GPUs, training models much faster. But it created a blind spot: permutation invariance. Mathematically, if you shuffle the input vectors, the output of a pure attention layer remains statistically similar unless something tells the model about order.
| Feature | RNNs (Sequential) | Transformers (Parallel) |
|---|---|---|
| Processing Method | One token at a time | All tokens simultaneously |
| Position Awareness | Inherent via time-step | Requires explicit injection |
| Training Speed | Slow (sequential dependency) | Fast (parallelizable) |
| Long-Range Dependency | Struggles with long gaps | Direct connection possible |
Without positional data, the model sees a bag of words, not a sentence. It doesn’t know that "not" modifies the verb that follows it rather than the noun before it. To fix this, engineers inject position-specific vectors into the word embeddings before the data hits the first Transformer layer.
Absolute vs. Relative: The Early Struggles
The initial solution was straightforward: Absolute Position Embeddings (APEs). Each position in the sequence gets a unique ID (0, 1, 2, etc.), and the model learns a vector for each ID. These vectors are added to the word embeddings. So, the embedding for "cat" at position 3 looks different from "cat" at position 10.
This worked well enough for short texts, but it broke down at scale. A major study by Meta AI Research in December 2022 revealed a critical flaw. When researchers shifted the starting position of sentences-essentially asking the model to start counting from 100 instead of 0-performance dropped by an average of 23.7%. In some cases, accuracy plummeted by 38.2%.
Why? Because APEs teach models to over-rely on fixed coordinates. If a model only ever saw the start of a sentence at position 0, it got confused when that context appeared at position 50. It treated position as a hard constraint rather than a relational cue. This limitation highlighted the need for methods that focus on the distance between words, not just their absolute location.
The Rise of Rotary Position Embedding (RoPE)
Enter Rotary Position Embedding (RoPE), which has become the dominant standard in modern LLMs like LLaMA and GPT. Instead of adding a static vector to the word embedding, RoPE rotates the query and key vectors in the attention mechanism based on their relative position.
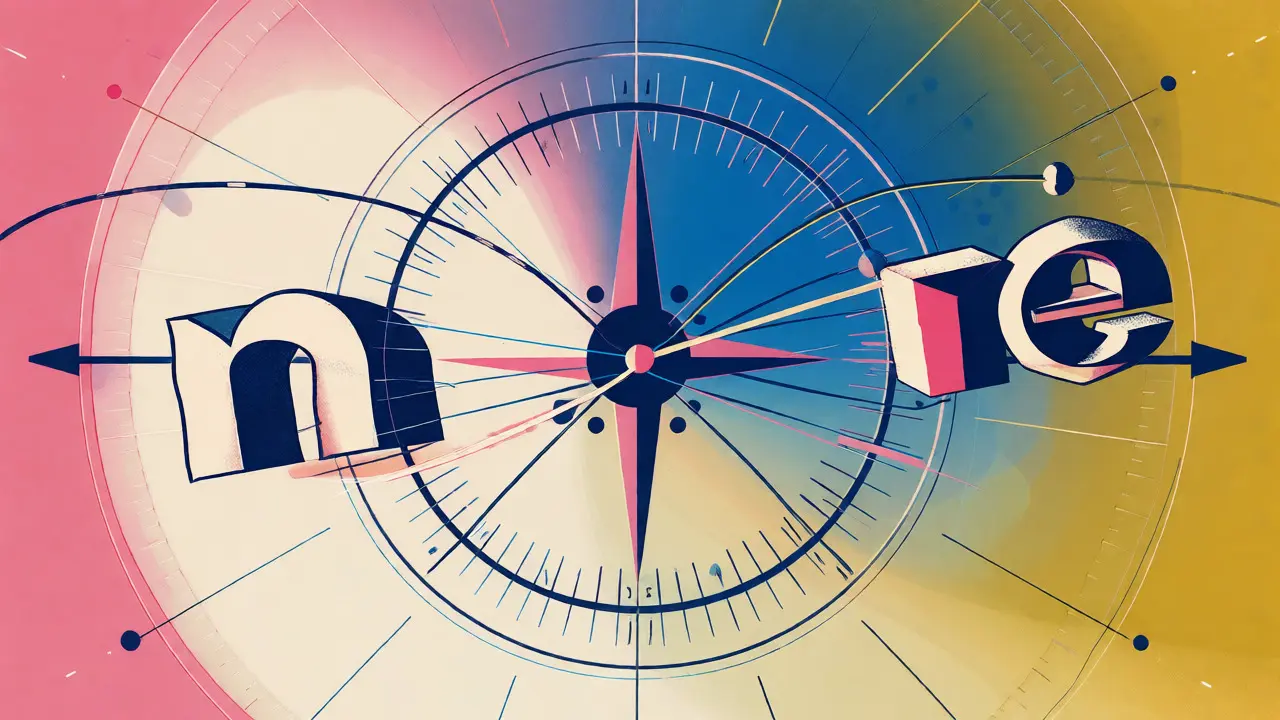
Think of it like a clock face. If two words are four positions apart, their vectors are rotated by a specific angle corresponding to that distance. If they are ten positions apart, the rotation is larger. This encodes relative distance directly into the attention scores. The beauty of RoPE is its extrapolation capability. Models using RoPE, such as LLaMA-2, showed only a 4.7% increase in perplexity when processing sequences twice as long as those seen during training. Compare that to the 21.3% degradation seen with absolute embeddings, and the advantage becomes clear.
By December 2025, 87% of top-performing models on the Hugging Face Open LLM Leaderboard utilized RoPE variants, up from just 32% in early 2023. The industry voted with its feet, favoring relative stability over absolute rigidity.
Limitations of Fixed Rotations
Despite its success, RoPE isn’t perfect. Its core assumption is that the importance of position depends solely on distance. Words four positions apart always receive the same rotational treatment, regardless of what those words actually mean. This works fine for English, where syntax is relatively rigid. But it struggles with languages that have flexible word orders, like Latin or Japanese, where meaning relies heavily on contextual relationships rather than fixed distances.
Research from MIT in December 2025 pointed out this exact issue. Professor David Bau argued that RoPE is independent of the input data-it applies a mathematical rule without looking at semantics. His team proposed a concept called "positional memory," which tracks how meaning changes along the path between words. In tests involving long-context reasoning, this approach improved accuracy by 4.2% compared to standard RoPE. It suggests that future models might need to blend geometric rotations with semantic-aware positioning.
Another interesting finding comes from a 2025 arXiv study on "position generalization." It showed that transposing up to 5% of word positions in input text caused only marginal performance drops (1.8-3.2%). GPT-4, for instance, degraded by just 1.9% on GLUE benchmark tasks despite significant shuffling. This implies that while position matters, modern LLMs are surprisingly robust against minor disorder, likely because they learn strong semantic associations that partially override strict positional rules.
Balancing Position and Semantics
Implementing positional encoding isn’t just about picking an algorithm; it’s about balancing signals. If the positional signal is too strong, it can cause "attention collapse," where the model ignores the actual meaning of words in favor of their location. IBM’s technical documentation warns that improper scaling can lead to this, especially in sequences exceeding 4096 tokens.
The optimal balance varies by task. For language modeling, where predicting the next word is key, research suggests a weighting of 67-73% semantic information versus 27-33% positional information. However, for structured reasoning tasks-like solving math problems or parsing code-the positional weight needs to be higher, around 58-62%. This makes sense: logic often depends on strict order, whereas natural language allows for more flexibility.
Developers also face a dilemma regarding distance decay. Human intuition suggests nearby words are more relevant, so many encodings bake in a decay function. But recent studies argue this assumption may be outdated. Modern attention mechanisms can effectively link distant concepts if the semantic relationship is strong. Baking in too much distance bias might actually hinder models that need to connect a subject at the start of a paragraph with its verb three sentences later.
Key Takeaways
- Parallelism requires help: Transformers process tokens simultaneously, so they need explicit positional data to understand word order.
- Absolute embeddings fail at scale: They struggle with length extrapolation and shift sensitivity, leading to significant performance drops.
- RoPE is the current standard: It encodes relative distance via rotation, offering better generalization to longer sequences.
- Context matters more than distance: Newer research suggests that semantic-aware positioning may outperform purely geometric methods in flexible languages.
- Robustness exists: Modern LLMs can tolerate minor word shuffles, indicating that semantic strength can sometimes compensate for positional noise.
Frequently Asked Questions
Why can't Transformers just learn word order on their own?
The self-attention mechanism in Transformers is mathematically permutation invariant. This means if you shuffle the input tokens, the output distribution remains largely unchanged unless you explicitly add positional information. Without this injection, the model treats the input as a set of words rather than a sequence, losing the syntactic structure required for grammar and meaning.
What is the main disadvantage of Absolute Position Embeddings?
Absolute Position Embeddings (APEs) suffer from poor extrapolation beyond training lengths and over-reliance on fixed positions. Studies show that shifting the starting position of a sentence can cause accuracy drops of over 30%, as the model fails to recognize patterns it learned at different coordinate indices.
How does Rotary Position Embedding (RoPE) differ from other methods?
RoPE encodes relative position by applying rotation matrices to query and key vectors based on the distance between tokens. Unlike absolute embeddings that add a static vector, RoPE integrates position into the attention calculation itself, allowing for better handling of variable-length sequences and improved extrapolation capabilities.
Do LLMs care if I scramble the word order slightly?
To a degree, yes. Recent research indicates that transposing up to 5% of word positions results in only marginal increases in perplexity (1.8-3.2%). Modern models like GPT-4 show high robustness to minor shuffling, suggesting that strong semantic associations can partially compensate for positional errors.
Which languages benefit most from advanced positional encoding?
Languages with flexible word orders, such as Latin, Japanese, or Russian, benefit significantly from context-aware positional encoding. Standard RoPE assumes fixed distance relevance, which can misinterpret meaning in these languages. Emerging "positional memory" techniques that account for semantic paths offer better performance here.
Next Steps for Developers
If you’re building or fine-tuning an LLM, start by checking your architecture’s positional encoding type. If you’re using older models with Absolute Position Embeddings, consider testing with shifted inputs to gauge sensitivity. For new projects, default to RoPE or its variants unless you are working specifically with highly flexible grammatical structures. Keep an eye on hybrid approaches combining RoPE with semantic attention weights, as Gartner predicts these will dominate enterprise deployments by 2027.