You’ve built a Retrieval-Augmented Generation (RAG) system. You indexed your data, set up vector embeddings, and wired it to a Large Language Model (LLM). But when you ask a specific question, the answer is still off. Maybe it’s vague, maybe it misses a critical detail buried in page 42 of a PDF, or worse, it hallucinates because it ignored the one document that actually had the answer.
Here’s the hard truth: vector similarity alone is not enough. It’s fast, sure, but it’s shallow. It matches shapes in mathematical space, not meaning in human context. This is where document re-ranking enters the picture. It’s the second stage of retrieval that acts as a quality filter, ensuring your LLM sees only the most relevant information. If you’re struggling with factuality control in your AI apps, re-ranking isn’t just an optimization-it’s often the difference between a toy demo and a production-ready tool.
The Problem With One-Stage Vector Search
Most modern RAG pipelines start with dense vector retrieval. You convert your documents into numerical vectors using an embedding model (like BERT or Sentence-BERT) and store them in a vector database. When a user asks a question, you embed that query and find the nearest neighbors. Simple, right?
But here’s the catch: this process compresses complex semantic relationships into fixed-length vectors. In doing so, it loses nuance. A vector search might rank a document highly because it shares keywords with the query, even if the context is wrong. Or it might miss a document entirely because the phrasing differs slightly, despite containing the exact answer. This gap between "topical resemblance" and "situational relevance" is where errors creep in.
Think of it like hiring. If you screen resumes by looking for the word "Python," you’ll get hundreds of candidates. Some are Python experts; others just mentioned Python in a hobby section. Vector search gives you the list of everyone who mentioned Python. Re-ranking reads their actual experience to tell you who can actually code in Python.
How Two-Stage Retrieval Works
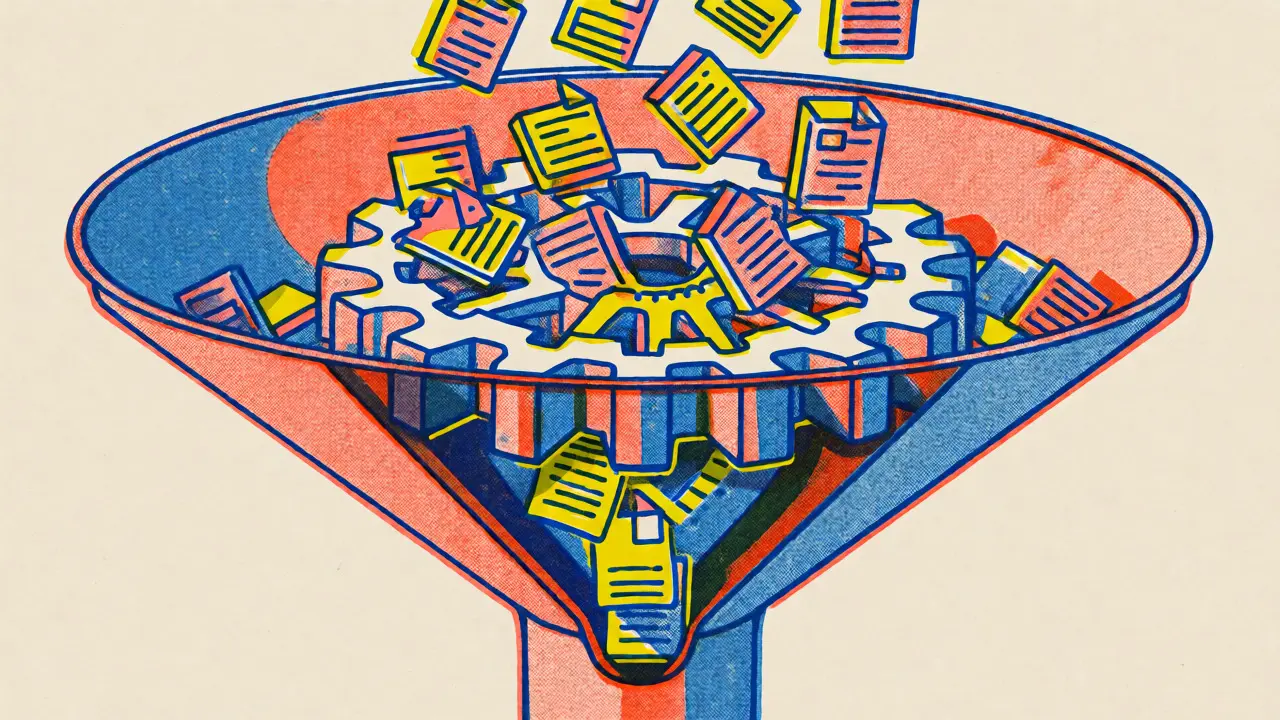
To fix this, we use a two-stage architecture. The first stage is about recall-getting all possible relevant documents quickly. The second stage is about precision-sorting those documents accurately.
| Feature | Initial Retrieval (Vector Search) | Re-Ranking (Cross-Encoder) |
|---|---|---|
| Method | Bi-Encoder (Independent embeddings) | Cross-Encoder (Joint processing) |
| Speed | Extremely Fast (milliseconds) | Slower (requires inference per pair) |
| Accuracy | Moderate (misses nuances) | High (captures deep semantics) |
| Input Size | Entire Index (millions of docs) | Top-K Candidates (10-50 docs) |
| Cost | Low | High (compute-intensive) |
In the first stage, you retrieve a larger candidate set-say, the top 20 or 50 documents. This ensures you don’t miss the needle in the haystack. Then, instead of feeding all 50 chunks directly to the LLM (which wastes tokens and confuses the model), you pass them through a re-ranker.
The re-ranker uses a Cross-Encoder a transformer model that processes the query and document together to predict a relevance score. Unlike bi-encoders, which compute embeddings separately, a cross-encoder looks at the interaction between every token in the query and every token in the document. This allows it to understand things like negation, sarcasm, and specific entity relationships that simple cosine similarity misses.
Why Cross-Encoders Beat Bi-Encoders for Precision
The magic of re-ranking lies in the architecture. A bi-encoder (used in initial retrieval) creates a single vector for the query and a single vector for the document. It then calculates the distance between these two points. It’s efficient but blind to fine-grained interactions. If a document says "The cat did not sit on the mat," and the query is "Did the cat sit on the mat?", a weak embedding might see high overlap in words and rank it highly, missing the crucial "not."
A cross-encoder, however, feeds both texts into the model simultaneously. The attention mechanism in the transformer layers can explicitly link the word "did" in the query to the word "not" in the document. It computes a joint representation that captures the contradiction. This results in a much more accurate relevance score.
This approach maximizes mutual information $I(Q;D)$ between the query $Q$ and the selected documents $D$. By reducing uncertainty about which documents truly answer the prompt, you lower the chance of the LLM generating facts based on irrelevant noise. In practical terms, this means fewer hallucinations and higher factual consistency.
Implementing Re-Ranking in Your Pipeline
So, how do you actually add this to your stack? You don’t need to rewrite your entire application. Most vector databases and orchestration frameworks support pluggable retrievers.
- Select a Re-Ranker: Popular choices include models from Hugging Face like
cross-encoder/ms-marco-MiniLM-L-6-v2or specialized APIs like Cohere Rerank or Jina Reranker. For enterprise-grade setups, NVIDIA’s NeMo Retriever offers optimized microservices. - Adjust Top-K Parameters: Increase your initial retrieval limit (e.g., from 5 to 20). You want enough candidates for the reranker to sift through, but not so many that latency spikes.
- Integrate the Step: After the vector search returns IDs and scores, pass the top-N documents and the original query to the reranker. Get back new scores and reorder your list.
- Truncate for LLM: Take only the top 3-5 documents after re-ranking. These are the ones you inject into the LLM’s context window.
Consider the trade-off carefully. Re-ranking adds latency. Each query-document pair requires a forward pass through a transformer model. If you’re re-ranking 20 documents, that’s 20 inferences. For a real-time chatbot, this might add 100-300ms. Is that acceptable? Usually, yes, because the alternative is answering incorrectly.
Advanced Techniques: Agentic and Multimodal Reranking
The field hasn’t stood still. Basic cross-encoders are great, but researchers are pushing boundaries with agentic approaches. Take JudgeRank, for example. Instead of just scoring, it mimics human reasoning: analyzing the query, summarizing the document in relation to the query, and then judging relevance. This multi-step process has shown superior performance on benchmarks like BRIGHT, especially for complex, multi-hop questions.
Multimodal data presents another challenge. If your knowledge base includes images, charts, or tables alongside text, standard text embeddings fail. Here, relevancy score measures designed for multimodal RAG become critical. Systems using CLIP-based embeddings for image-text pairs often struggle with precise alignment. Adaptive selection mechanisms that dynamically choose the number of retrieved entries ($k$) rather than using a fixed number help mitigate this by filtering out low-confidence matches before they reach the LLM.
Common Pitfalls and How to Avoid Them
Don’t fall into the trap of over-re-ranking. If you feed 100 documents to a heavy cross-encoder, your latency will kill user experience. Stick to reasonable candidate sets (10-50).
Also, beware of domain mismatch. A general-purpose reranker trained on web search queries might perform poorly on legal contracts or medical records. Fine-tuning a smaller cross-encoder on your specific domain data can yield massive improvements in accuracy without the cost of training a full LLM.
Finally, monitor your metrics. Don’t just look at end-to-end response quality. Track retrieval recall (did we get the right doc?) and LLM faithfulness (did the model stick to the doc?). Re-ranking improves the former, which indirectly boosts the latter. If your LLM is still hallucinating despite perfect retrieval, the issue might be prompt engineering or model capacity, not retrieval.
Is document re-ranking worth the extra latency?
Yes, for most production applications. While it adds computational overhead, the improvement in answer accuracy and reduction in hallucinations usually outweighs the slight delay. Users prefer waiting an extra 200ms for a correct answer over getting an instant but wrong one.
Can I use an LLM itself as a reranker?
You can, but it’s expensive. Using a large model like GPT-4 to score relevance for 20 documents involves significant token usage and cost. Specialized cross-encoder models are much cheaper and faster for this specific task, reserving the big LLM for final generation.
How many documents should I retrieve initially?
A common rule of thumb is to retrieve 10-20 times more documents than you plan to feed to the LLM. If you send 5 documents to the LLM, retrieve 50-100 initially. This gives the reranker enough options to find the best matches without overwhelming the system.
Does re-ranking work for multimodal data?
Standard text rerankers struggle with pure visual data. However, multimodal rerankers that process image-text pairs jointly exist. For mixed content, ensure your reranker supports the modalities present in your index, or preprocess non-text elements into descriptive captions before retrieval.
What is the difference between BM25 and vector search in this context?
BM25 is a keyword-based lexical search method, while vector search is semantic. Both can serve as the initial retrieval stage. Hybrid search (combining BM25 and vectors) often provides the best starting candidate set for re-ranking, as it catches both exact keyword matches and semantic similarities.
Nnaemeka Anadu
19 November, 2026 - 09:36 AM
you think this is new? vector search was always a lazy shortcut for people too scared to actually read the docs. cross encoders are just brute force pretending to be intelligence. its like trying to fix a broken window by buying a bigger house. you dont need fancy rerankers if your data is garbage in the first place. most of these "hallucinations" are just bad prompting and poor chunking strategies that nobody wants to admit they messed up. stop blaming the retrieval method when the foundation is rotting. its all smoke and mirrors sold by vendors who charge per inference.
kevin montesinos valencia
20 November, 2026 - 05:48 AM
This is such a helpful breakdown! I’ve been struggling with my RAG pipeline lately, especially with those tricky negation cases mentioned in the article. The analogy about hiring candidates really clicked for me because it makes the difference between keyword matching and semantic understanding so clear. I’m definitely going to try adjusting my Top-K parameters as suggested. It feels good to know there’s a practical solution that doesn’t require completely rebuilding everything. Thanks for sharing this!