Imagine a lawsuit hits your company next month. The plaintiff claims your customer service bot gave bad advice that cost them thousands. Your legal team asks a simple question: "What exactly did the AI say, what data did it see, and why did it make that choice?" If you can’t answer in seconds, you’re in trouble. Generative AI recordkeeping is not just an IT chore; it’s your legal shield.
Most companies treat AI logs like trash-write them, store them somewhere, and forget them. That’s a mistake. With regulations like the EU AI Act tightening, you need a solid plan for logging, keeping records, and finding them when lawyers come knocking. Here is how to build a system that actually works.
Why Standard Logs Don't Cut It for GenAI
Traditional software logs tell you if a server crashed or a database timed out. They don’t tell you why a large language model (LLM) hallucinated a fact. For generative AI, you need decision provenance. This means capturing the full story of a single interaction.
You must log three specific things:
- The Prompt: Exactly what the user typed, including any hidden system instructions.
- The Context: What documents or data chunks were retrieved from your vector database?
- The Output: The final text generated by the model, plus confidence scores if available.
If you skip this, you have a black box. And nobody trusts a black box in court. You need structured JSON logs, not messy text files. Why? Because machines can read JSON fast, but humans can also scan it quickly during an audit.
Designing Your Logging Strategy
You can’t log everything. If you try to capture every token generated by every user, your storage bill will explode. You need a smart sampling strategy. Think of it like security cameras: you record everything at the front door, but only motion-triggered clips in the hallway.
Here are four practical approaches to balance detail with cost:
| Strategy | How It Works | Best For |
|---|---|---|
| Rate-Based | Log 1 out of every N requests (e.g., 1% of all chats). | High-volume consumer apps where average behavior matters more than edge cases. |
| Event-Based | Only log errors, timeouts, or low-confidence responses. | Troubleshooting and quality assurance teams. |
| Anomaly-Based | Use ML to flag unusual inputs or outputs and log those. | Fraud detection or security-sensitive applications. |
| User-Centric | Log 100% of interactions for high-value enterprise clients. | B2B services where individual client disputes are common. |
Start with event-based logging. Capture every error and every time the model says "I don't know." Once your system stabilizes, move to rate-based sampling for normal traffic. This keeps your costs down while ensuring you never miss a critical failure.
Retention Policies: How Long Should You Keep Data?
This is the million-dollar question. How long do you keep those logs? There is no one-size-fits-all answer, but there are rules of thumb based on risk.
For most businesses, a tiered approach works best:
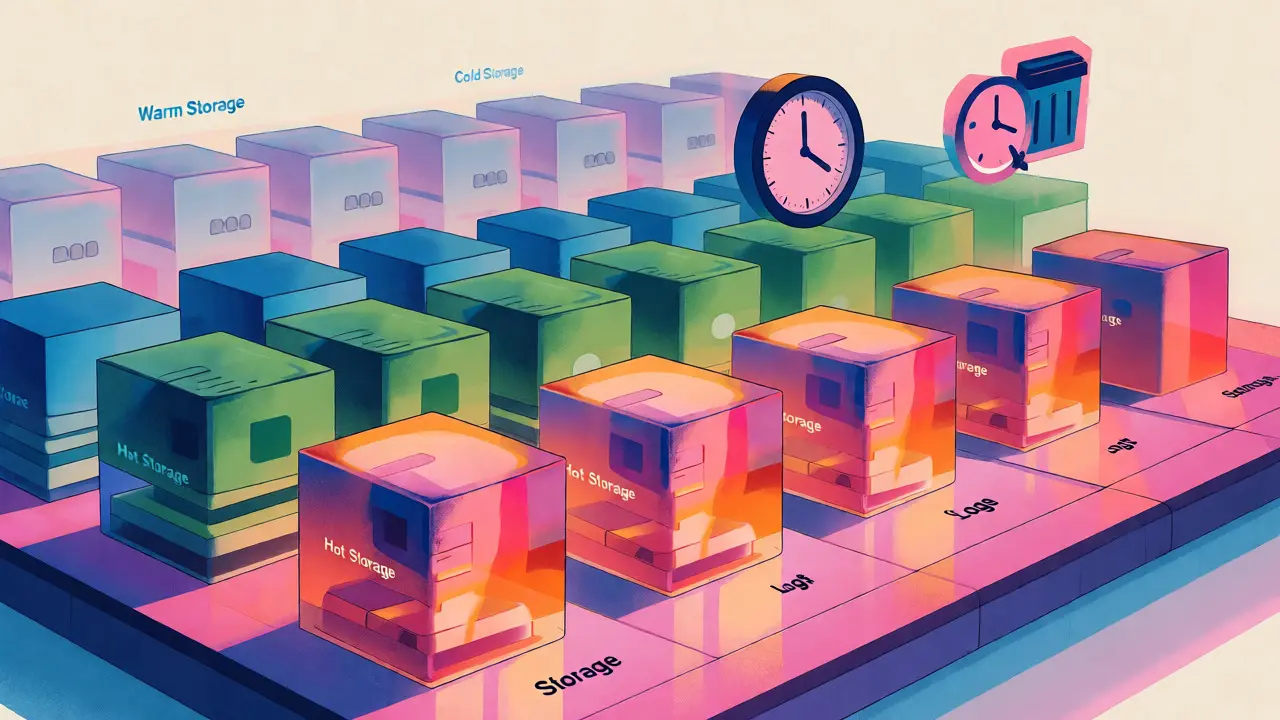
- Hot Storage (30-90 days): Full detail logs available for immediate troubleshooting. Fast access, higher cost.
- Warm Storage (6-12 months): Compressed logs for trend analysis and quarterly audits. Slower access, lower cost.
- Cold Storage (3-7 years): Archived summaries or sampled data for long-term compliance and historical pattern recognition. Cheapest option, slowest retrieval.
Check your industry regulations. Healthcare (HIPAA) and finance (SOX) often require longer retention periods than retail or tech. Also, consider the statute of limitations for contracts in your region. If a customer can sue you five years after using your AI tool, you might need records from year one.
Don’t forget privacy. In Europe, the General Data Protection Regulation (GDPR) gives users the right to be forgotten. Your retention policy must include a mechanism to delete personal identifiers from logs upon request, even if you keep the anonymized usage data.
E-Discovery: Finding Needles in Haystacks
When litigation starts, lawyers issue e-discovery requests. They want emails, documents, and now, AI logs. If your logs are unstructured text blobs, your legal team will spend weeks searching through gigabytes of data. They’ll miss key evidence. Or worse, they’ll find nothing because the search terms didn’t match the raw format.
To survive e-discovery, your logs need consistent metadata. Every entry should have:
- Unique Request ID: A UUID that ties the prompt, context, and output together.
- Timestamp: Precise to the millisecond, in UTC.
- User Identifier: Hashed user IDs to protect privacy while allowing tracking.
- Model Version: Which version of the LLM was used? Models change over time, and their behavior shifts.
Use tools that support full-text search across these fields. Platforms like Sumo Logic or Graylog can cluster similar log entries, helping you spot patterns. Imagine you get a complaint about biased hiring advice. Instead of reading every log, you filter by "model_version_2.1" and "prompt_type=interview_question," then review the flagged anomalies.
Remember, chain of custody matters. If you alter logs after they are written, their legal value drops. Use write-once storage options where possible, or maintain cryptographic hashes of your log batches to prove they haven’t been tampered with.
Governance: Making It Part of the Workflow
Recordkeeping fails when it’s treated as an afterthought. Developers ship code, then someone tries to add logging later. By then, it’s too hard. Integrate logging into your CI/CD pipeline. Make it mandatory for any new AI feature to pass a "logging check" before deployment.
Collaboration is key. Data scientists care about accuracy metrics. Legal teams care about liability. Ops teams care about uptime. They speak different languages. Create a shared dashboard that shows both performance stats and compliance flags. When everyone sees the same data, decisions become faster and less contentious.
Regularly test your recovery process. Pretend you lost last week’s logs. Can you reconstruct a decision from backups? Run drills twice a year. It sounds tedious, but it beats discovering your backup system failed during a real crisis.
Common Pitfalls to Avoid
Even experienced teams mess this up. Here are the top traps:
- PII Leakage: Accidentally logging credit card numbers or SSNs in prompts. Always scrub sensitive data before storing logs.
- Inconsistent Formats: One team uses JSON, another uses CSV. Merging them later is a nightmare. Standardize early.
- Ignoring Model Drift: Not logging which model version handled each request. If you update your model, old logs become misleading without version tags.
- Over-Logging: Storing every intermediate reasoning step for every query. Unless you’re debugging a specific issue, this bloats storage unnecessarily.
Avoid these by automating checks. Set alerts if PII appears in logs. Enforce schema validation in your logging library. Review storage growth monthly.
Final Thoughts
Good recordkeeping isn’t about hoarding data. It’s about building trust. When you can show exactly how your AI made a decision, customers feel safer. Regulators feel respected. Lawyers back off. Start small, define your critical events, and scale up as you learn. Your future self-and your legal counsel-will thank you.
Do I need to log every single AI interaction?
No, logging every interaction is often too expensive and noisy. Use sampling strategies like rate-based or event-based logging to capture significant events, errors, or a representative subset of traffic, balancing detail with storage costs.
How does GDPR affect AI log retention?
GDPR grants users the right to erasure. Your retention policy must allow for the deletion of personal identifiers from logs upon user request, even if you retain anonymized usage data for analysis. Ensure your systems can identify and remove PII efficiently.
What format is best for AI logs?
Structured formats like JSON are recommended. They are machine-parseable for automated analysis and human-readable for audits. Include standardized fields such as timestamps, unique request IDs, model versions, and log levels.
Why is model versioning important in logs?
AI models evolve. Behavior changes between versions. Logging the specific model version used for each request allows you to correlate issues with updates and ensures accurate root cause analysis during e-discovery or troubleshooting.
Can AI help manage my own logs?
Yes, AI-driven tools can cluster similar log entries, detect anomalies, and summarize patterns. This reduces manual review time and helps identify recurring issues or outliers in large datasets more efficiently than traditional keyword searches.