You’ve probably noticed it. You ask a large language model (LLM) a complex question in English, and it nails the answer with surgical precision. Then you switch to Spanish, Hindi, or Swahili, and suddenly the model gets fuzzy. It hallucinates facts, misses nuance, or just sounds like a bad translation of a textbook. This isn’t magic; it’s math. Most major LLMs are trained on massive datasets where English dominates. When you prompt in other languages, you’re asking the model to perform in its second-or third-language.
Multilingual prompting is the practice of strategically mixing languages within your prompts to fix this performance gap. It’s not about translating everything blindly. It’s about knowing which parts of the prompt need to stay in the target language and which parts should be converted to English to leverage the model’s strongest reasoning capabilities. Research from Bar-Ilan University and industry leaders like ModernMT shows that getting this right can boost accuracy by over 10 points without changing a single line of code or retraining the model.
Why Your LLM Struggles Outside English
Let’s look at why this happens. Benchmarks like MultiChallenge reveal a stark reality: models trained primarily on English web data suffer significant drops in robustness when handling low-resource or typologically distant languages. The issue isn’t just vocabulary; it’s structural. Tokenization for scripts like Arabic or Devanagari is often less efficient than for Latin-based alphabets. Morphology-how words change form-is harder for the model to track if it hasn’t seen enough examples during training.
This leads to what experts call "brittleness." A model might understand a simple greeting in French perfectly but fail completely when asked to extract specific entities from a legal contract in Portuguese. The underlying weights haven’t changed, but the signal-to-noise ratio has shifted. If you treat every language equally in your prompts, you’re fighting against the model’s own training bias. Multilingual prompting aligns your instructions with how the model actually thinks.
The Cross-Lingual Thought Method
One of the most effective techniques to emerge recently is Cross-Lingual Thought (XLT). Introduced in research around 2023, XLT doesn’t require fine-tuning. Instead, it uses a specific prompt template that forces the model to use English as an internal "reasoning language" while keeping the user interface in the target language.
Here’s how it works conceptually:
- Role Assignment: Tell the model it is an expert in the target language (e.g., "You are an expert legal assistant fluent in Brazilian Portuguese").
- Internal Translation: Instruct the model to internally translate the user’s query into English.
- Step-by-Step Reasoning: Ask the model to solve the problem using chain-of-thought reasoning in English.
- Final Output: Require the final answer to be generated strictly in the target language.
By decoupling the reasoning process (done in English) from the output format (in the target language), you bypass many of the limitations of non-English tokenization. Studies show this approach can yield over 10-point improvements in arithmetic reasoning and open-domain question answering across various languages. It effectively lets the model think in its strongest language while speaking in yours.
Selective Pre-Translation: Don’t Translate Everything
A common mistake is assuming that translating the entire prompt into English always helps. It doesn’t. A 2025 study by researchers at Bar-Ilan University analyzed "selective pre-translation" and found that different task types require different strategies. They broke prompts down into four components: instructions, context, examples, and output language.
For extractive tasks like Question Answering (QA) or Named Entity Recognition (NER), translating the source text (context) into English often hurts performance. Why? Because translation can distort exact spans of text. If you’re looking for a specific date or name in a German document, translating the whole document to English first might shift the word boundaries, making extraction harder. The research suggests keeping the context and examples in the source language for these tasks. However, for generative tasks like summarization, the opposite is true. Translating instructions and context into English before generating the summary usually yields better results, especially for low-resource languages. The model’s generative fluency is simply higher in English.
| Prompt Component | Extractive Tasks (QA, NER) | Generative Tasks (Summarization) |
|---|---|---|
| Instructions | Flexible (English or Source) | Translate to English |
| Context/Source Text | Keep in Source Language | Translate to English |
| In-Context Examples | Keep in Source Language | Translate to English |
| Output Language | Source Language (or English labels for NER) | Generate in English, then translate back |
Using Multiple Languages to Reduce Hallucinations
There’s another angle to multilingual prompting: diversity. A recent arXiv paper demonstrated that prompting in multiple languages simultaneously can reduce hallucination rates. When you ask an LLM a question only in English, it draws from a specific slice of its probability distribution. By prompting in both English and the target language (e.g., Thai), and then aggregating the answers, you force the model to cross-reference its knowledge.
This isn’t just about accuracy; it’s about richness. For creative brainstorming or complex analysis, providing inputs in two languages can uncover connections the model missed when operating in a single linguistic mode. It acts as a sanity check. If the model claims a fact exists in the English response but contradicts itself in the Spanish response, you know there’s likely a hallucination or ambiguity. This technique turns language choice into a control dial for confidence.
Production Pipelines: The T-LM Approach
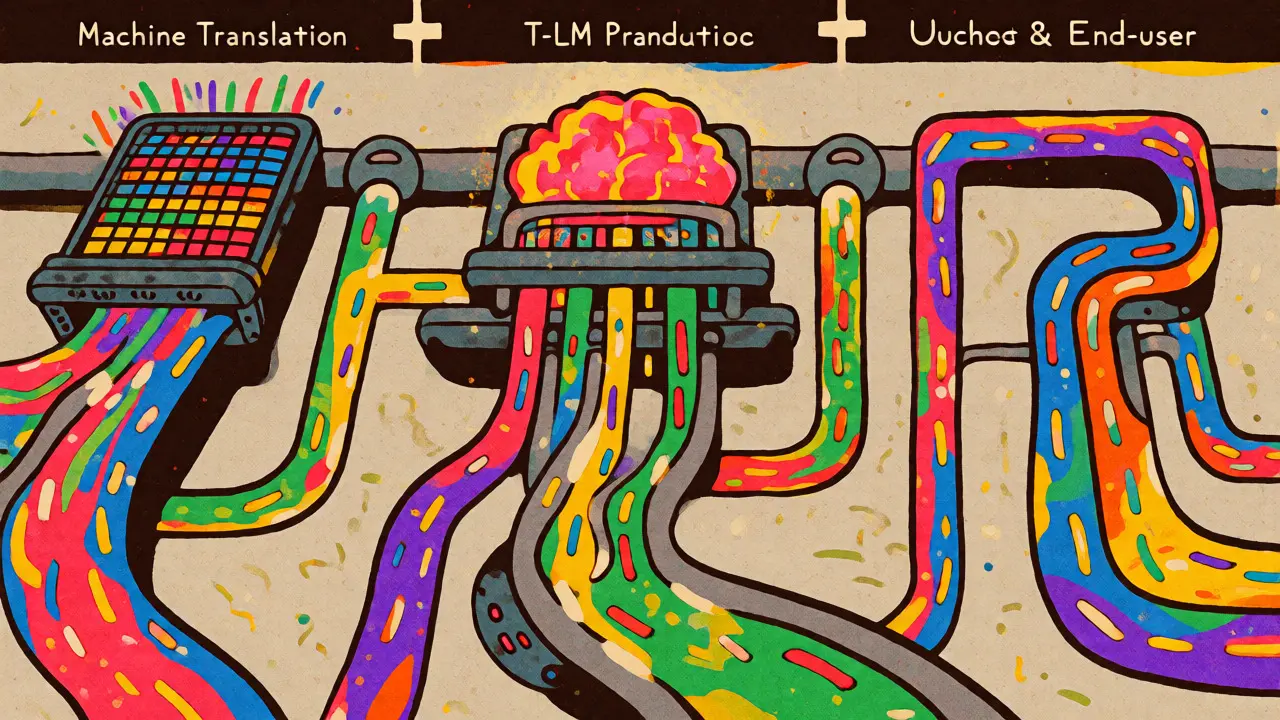
If you’re building enterprise software, you might not want to rely on the LLM’s internal translation skills alone. Companies like ModernMT have deployed systems like T-LM, which wraps the LLM in external machine translation layers. Here, a dedicated Machine Translation (MT) engine translates the user’s non-English prompt into high-quality English. The LLM processes it using standard English prompts (perhaps even using XLT templates). Finally, another MT engine translates the output back to the user’s language.
This pipeline separates concerns. You get the best of both worlds: specialized, domain-adapted translation for input/output, and raw, powerful reasoning from the LLM in its native tongue. The downside? Latency and dependency on MT quality. If your translator makes a mistake, the LLM will confidently generate a wrong answer based on that mistake. But for customer support bots dealing with dozens of languages, this consistency is often worth the trade-off.
Practical Checklist for Better Non-English Outputs
Ready to tweak your prompts? Start here:
- Define the Role Clearly: Always specify the target language and the persona. "Act as a medical consultant fluent in Mandarin."
- Choose Your Reasoning Language: For complex logic, instruct the model to "think in English" before answering in the target language.
- Respect Context Boundaries: Do not translate long source documents for extraction tasks. Keep them in their original script.
- Use English Labels for NER: Even if the text is in Arabic, ask the model to tag entities using standard English categories (PERSON, ORG, LOC) to improve consistency.
- Test Low-Resource Languages Differently: What works for French might fail for Swahili. Benchmark your prompts specifically for the languages you serve.
Multilingual prompting isn’t a one-size-fits-all hack. It’s a nuanced engineering discipline. By respecting how LLMs process language, you can unlock significantly better performance for your global users without breaking the bank on custom models.
Does multilingual prompting work for all LLMs?
It works best for models heavily trained on English data, such as GPT-4, Claude, and Llama series. Models specifically optimized for multilingual use cases may see smaller gains, but the principles of separating reasoning from output still apply to improve clarity and reduce errors.
Should I always translate my prompts into English?
No. For extractive tasks like finding a specific date in a document, keeping the context in the source language is usually more accurate. Translation can alter word boundaries and nuances needed for exact matching. Use English for instructions and reasoning, but preserve source text for evidence.
What is Cross-Lingual Thought (XLT)?
XLT is a prompting technique where the model is instructed to internally translate the task into English, perform step-by-step reasoning in English, and then generate the final answer in the requested target language. This leverages the model's stronger English reasoning capabilities while serving non-English users.
How does multilingual prompting reduce hallucinations?
By prompting in multiple languages or using English for internal reasoning, you force the model to access different parts of its knowledge base. Aggregating responses from different linguistic perspectives can highlight inconsistencies, allowing you to filter out fabricated information that appears in one language but not the other.
Is selective pre-translation better than full translation?
Generally, yes. Full translation risks introducing errors from the machine translation system into the core reasoning process. Selective pre-translation keeps critical evidence in its original form while translating instructions to guide the model, resulting in higher accuracy for both extractive and generative tasks.